Choose your setup
AutoMem runs as a separate service. Choose where it runs, set how it creates embeddings, then connect the agents you use.
- 01 Run the service
Local, hosted, or already running.
- 02 Choose embeddings
Run a model on your hardware or use a hosted API.
- 03 Connect an agent
Use the same endpoint from each client.
Choose how embeddings run
Section titled “Choose how embeddings run”AutoMem uses embeddings to find memories by meaning. The server and the embedding model are separate choices. For example, an AutoMem server on Railway can compute embeddings on that server with FastEmbed, and a Docker install on your laptop can call Voyage or OpenAI.
| Where embeddings run | Set on the AutoMem server | What to plan for |
|---|---|---|
| On the server | EMBEDDING_PROVIDER=local uses FastEmbed. At 1024 dimensions it loads BAAI/bge-large-en-v1.5. | No embedding API fee. The server needs CPU, memory, and disk for inference and the model. |
| On an Ollama server you operate | EMBEDDING_PROVIDER=ollama, with a reachable OLLAMA_BASE_URL, an embedding model, and a matching VECTOR_SIZE. | Text goes to the Ollama server. Its hardware runs the model. |
| Via a hosted API | EMBEDDING_PROVIDER=voyage or openai, with the matching key and model settings. | Memory and search-query text used for embeddings goes to the provider. Provider usage and network requests apply. |
Choose an explicit provider before your first memory write. Set it in the server’s environment, or ask the operator of an existing endpoint which model it uses. The MCP client takes the AutoMem endpoint and token. Provider keys belong on the server.
With EMBEDDING_PROVIDER=auto, AutoMem tries Voyage, OpenAI, configured Ollama, then FastEmbed during initialization. For a fresh collection the default is 1024 dimensions, so FastEmbed loads BGE Large when it is the first available option. If FastEmbed cannot load in auto, placeholder vectors are the last resort and have no semantic meaning.
Changing a model or provider on an existing endpoint usually requires re-embedding, even when both models return the same number of dimensions. See Embedding Generation for the migration steps.
Connect your agent
Section titled “Connect your agent”Run the command from your setup route above or use the guided launcher:
curl -fsSL get.automem.ai | shChoose your endpoint, select agents, then review the configuration plan. Use Existing Endpoint if you started AutoMem manually. The Claude Code plugin and other MCP clients connect to that separate service with its API URL and, for authenticated endpoints, a token.
Verify it worked
Section titled “Verify it worked”Once the installer finishes, confirm the backend is healthy:
# Local Dockercurl http://localhost:8001/health
# Hosted / existing endpointcurl https://your-automem-url/health
A healthy response looks like this:
{ "status": "healthy", "falkordb": "connected", "qdrant": "connected", "memory_count": 0, "enrichment": { "status": "running", "queue_depth": 0 }, "graph": "memories"}| Field | Description |
|---|---|
status | Overall health: "healthy" or "degraded" |
falkordb | Graph store connection: "connected" or "disconnected" |
qdrant | Vector store connection: "connected" or "disconnected" |
memory_count | Total memories in the graph |
enrichment.status | Background worker state: "running" or "stopped" |
graph | FalkorDB graph name (default memories) |
/health skips the API token check, so a healthy response does not prove that your key is accepted. For a hosted endpoint, confirm the key with a request to an endpoint that checks it. A 401 Unauthorized response means the key was rejected:
curl -i "https://your-automem-url/recall?limit=1" \ -H "Authorization: Bearer YOUR_AUTOMEM_API_TOKEN"Try it end to end
Section titled “Try it end to end”Restart the agent you connected (quit and reopen — don’t just close the window), then:
- Ask it to check AutoMem health — this calls the
check_database_healthtool. - Ask it to remember something: “Remember that I prefer TypeScript over JavaScript for new projects.”
- In a fresh chat, ask “What are my language preferences?” — the memory should come back, retrieved via hybrid search.
What the installer does
Section titled “What the installer does”graph LR
A["1 · Detect<br/>OS, Node, Docker,<br/>Git, agent roots"] --> B["2 · Choose<br/>Hosted, Local,<br/>or Existing"]
B --> C["3 · Provision<br/>Deploy + health-check<br/>your AutoMem server"]
C --> D["4 · Wire agents<br/>Review the plan,<br/>then connect Codex,<br/>Claude Code, Cursor…"]
It is safe to run, and safe to re-run:
- Nothing is written until you approve a plan. The installer prints a full review — endpoint, API key status, and every file it will touch — and waits for a yes.
- Every changed file keeps a
.bakcopy, so you can always roll back. - Re-running is idempotent. Local server tokens are reused (not rotated), so a second run never invalidates agents you already connected.
Prerequisites
Section titled “Prerequisites”| Tool | When it’s needed |
|---|---|
| Node.js 20.19+, 22.13+, or 24+ and npm | Always (the installer and the MCP bridge run on it) |
| Docker + Git | Only if you choose the Local Docker path |
The launcher checks for Node and npm first and stops with a clear message if either is missing — it never dumps a stack trace at you.
Walk-through: the installer, prompt by prompt
Section titled “Walk-through: the installer, prompt by prompt”Here is exactly what you’ll see, and what each choice means.
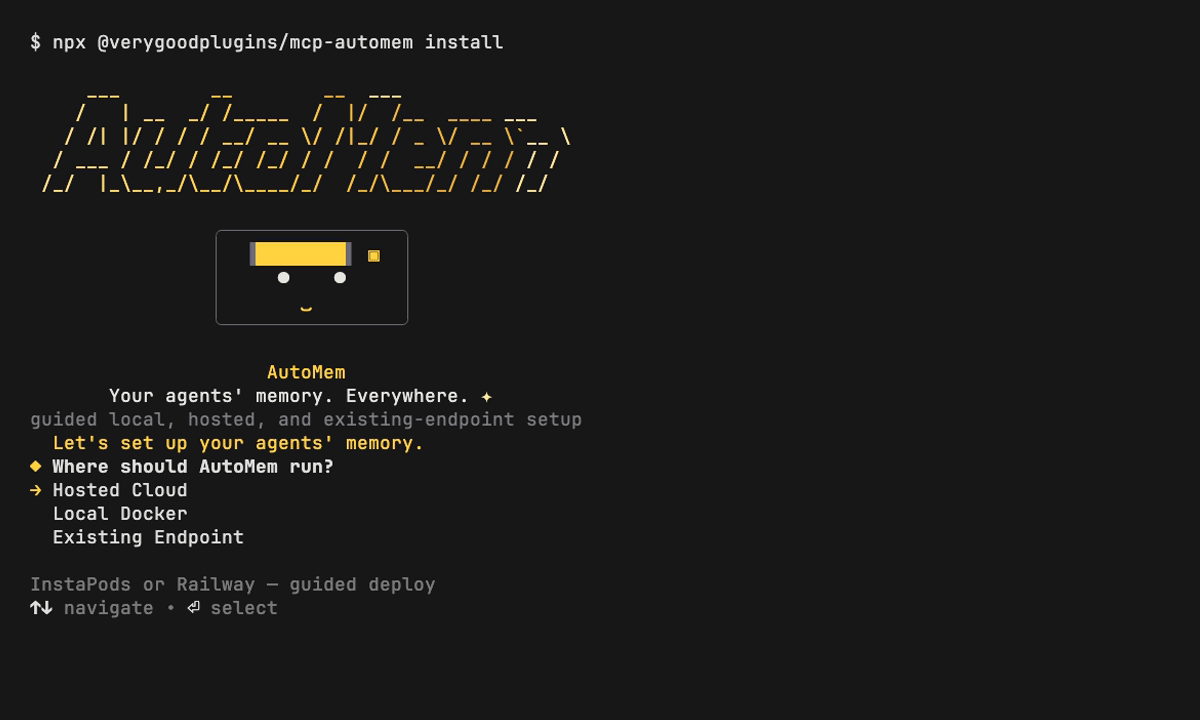
Splash → “Where should AutoMem run?”
Section titled “Splash → “Where should AutoMem run?””After a brief AutoMem splash, the first question picks your backend:
? Where should AutoMem run?❯ Hosted Cloud InstaPods or Railway — guided deploy Local Docker Clone AutoMem and start Docker Compose on this machine Existing Endpoint Use an AutoMem URL you already have| Option | Choose it when | What happens |
|---|---|---|
| Hosted Cloud (default) | You want one remote server for agents on multiple machines | InstaPods asks you to paste the URL and token. Guided Railway reads them after deployment. |
| Local Docker | You want to operate the server on your own machine | Clones AutoMem into ~/.automem/server, generates local tokens, runs docker compose up, and waits for /health |
| Existing Endpoint | You already run AutoMem somewhere | Paste the URL (and key); the installer verifies it before touching any agent config |
Hosted Cloud → pick a provider
Section titled “Hosted Cloud → pick a provider”Choosing Hosted Cloud asks how to stand it up:
? How should we stand up your hosted AutoMem?❯ InstaPods open the setup page — it deploys AutoMem and emails your URL + key Railway (guided) sign in with the railway CLI, deploy from the terminal, then auto-capture keys Other — I already have a URL + key already deployed somewhere; just paste your endpoint + token- InstaPods — opens the InstaPods setup page so you can deploy the pod, then asks you to paste the API URL and key you receive.
- Railway (guided) — signs in via the
railwayCLI and deploys the AutoMem template straight from the terminal, then reads the endpoint and token. It falls back to a browser deploy if the CLI can’t finish. - Other — you already have an endpoint; paste the URL + token and skip provisioning.
For Existing Endpoint (or Other), you’ll be prompted for the URL and a masked API key:
? AutoMem API URL › https://your-automem.example? AutoMem API key (leave blank if this endpoint does not require one) › ••••••••“Install AutoMem into which agents?”
Section titled ““Install AutoMem into which agents?””Next, choose which agents get wired up. Agents already detected on your machine are pre-checked — press space to toggle, enter to confirm:
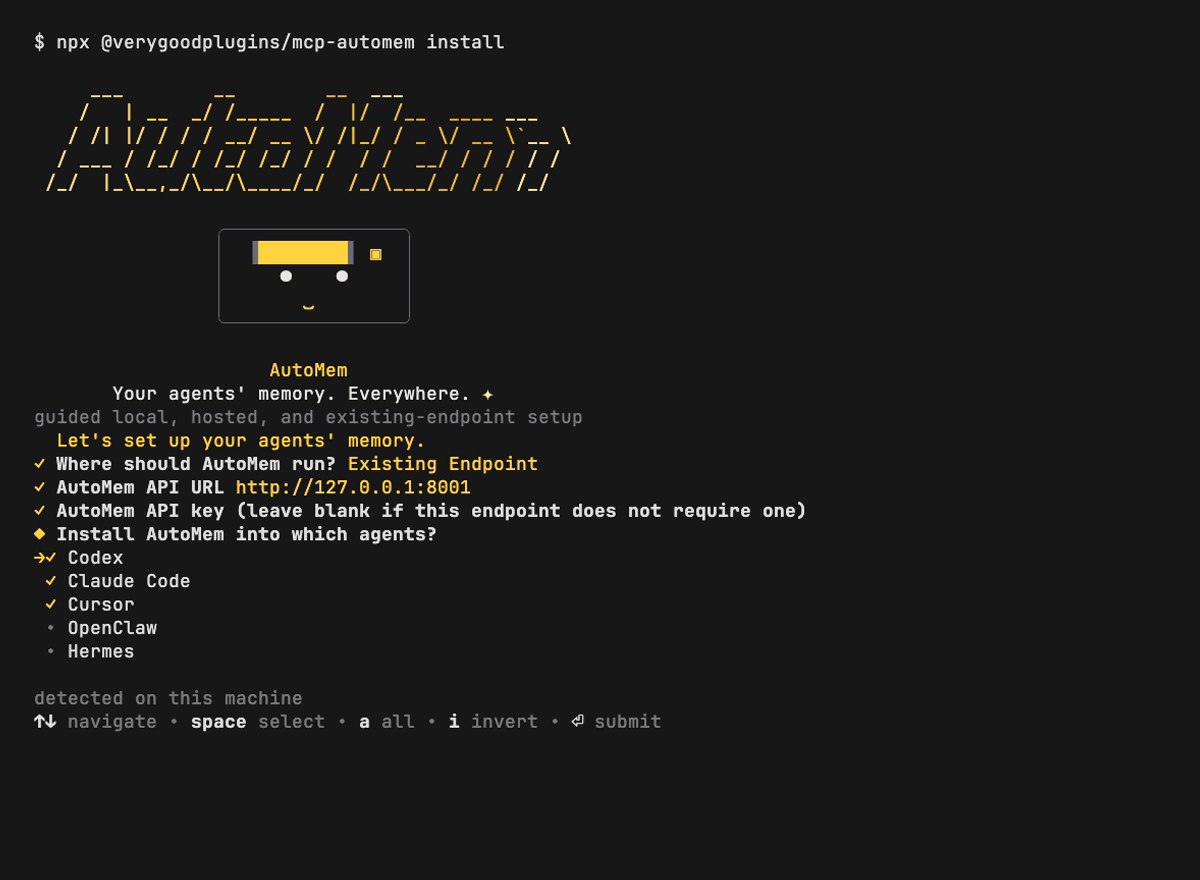
? Install AutoMem into which agents? (space to toggle, enter to confirm)❯ ◉ Codex detected on this machine ◉ Claude Code detected on this machine ◉ Cursor detected on this machine ◯ OpenClaw not detected, still installable ◯ Hermes not detected, still installable ◯ Grok not detected, still installableDetection looks for ~/.codex, ~/.claude, ~/.cursor, ~/.openclaw, ~/.hermes (override with $HERMES_HOME), and ~/.grok (override with $GROK_HOME). Anything not detected is still installable — just check it.
If you select Claude Code, it asks how to integrate:
? How should AutoMem integrate with Claude Code?❯ Plugin (recommended) bundles the MCP server + hooks, prompts for your endpoint, auto-updates Settings-level install writes ~/.claude hooks + permissions directly; no auto-update- Plugin (recommended) — adds the AutoMem marketplace and installs the plugin, which bundles the MCP server, hooks, and skill and auto-updates. If the
claudebinary is on your PATH the installer runsclaude plugin installfor you; otherwise it prints the two/plugincommands to run inside Claude Code. - Settings-level — writes
~/.claudehooks and permissions directly. Scriptable, but you update it yourself.
Selecting Hermes asks for a mode: Native memory provider (recommended — replaces Hermes’ built-in provider), MCP tools only (portable tools, no replacement), or Both.
Review the plan, then approve
Section titled “Review the plan, then approve”Before changing anything, the installer prints the full plan and waits for a yes:
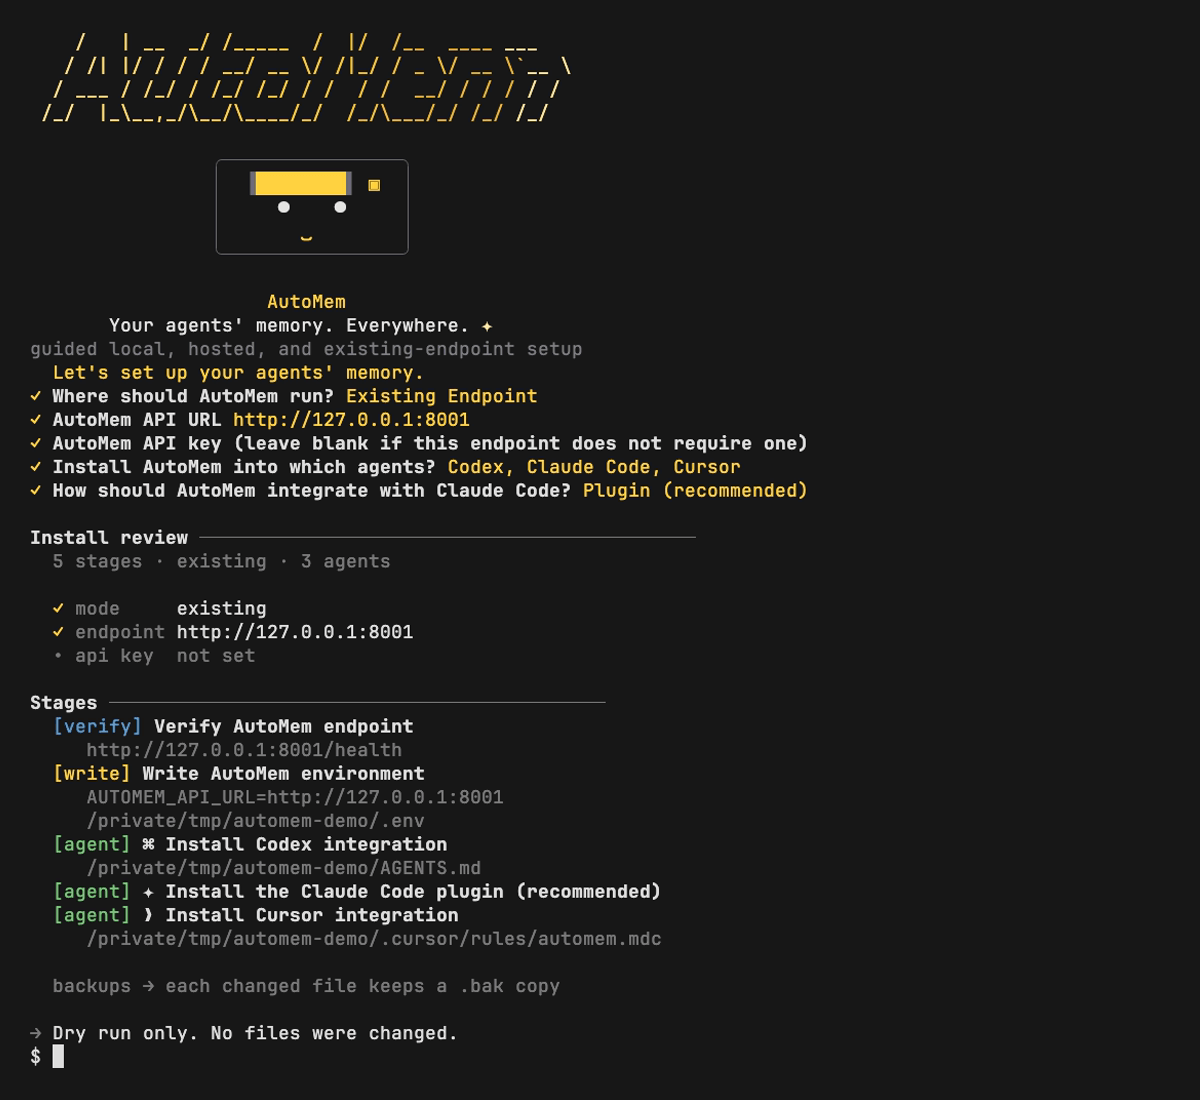
The plan lists the mode and endpoint, whether an API key is set (always shown redacted), and every stage it will run — verify the endpoint, write .env, and configure each agent — with the exact file paths it will touch. Every changed file keeps a .bak copy. (The screenshot above is a --dry-run, which prints the plan and stops without writing anything.)
Approve, and a live checklist ticks through each step — verify endpoint, write .env, configure each agent — finishing with a success card and your endpoint. If an individual agent needs a manual step (for example the OpenClaw CLI isn’t installed), that one is flagged with a copy-paste fix and the rest still complete.
Customize the install
Section titled “Customize the install”The installer is fully scriptable. Every prompt has a flag and an environment variable, so you can pre-answer some questions, automate the whole thing in CI, or preview a run without touching disk. Set environment variables before the pipe, or pass flags when calling the npm package directly.
# Hosted cloud, fully interactive (default)curl -fsSL get.automem.ai | sh
# Local Docker, no questions askedcurl -fsSL get.automem.ai | AUTOMEM_INSTALL_TARGET=local AUTOMEM_YES=1 sh
# Point at an endpoint you already run, only wire Codex + Cursorcurl -fsSL get.automem.ai | \  AUTOMEM_INSTALL_TARGET=existing \  AUTOMEM_API_URL=https://memory.example \  AUTOMEM_API_KEY=sk-... \  AUTOMEM_CLIENTS=codex,cursor \  AUTOMEM_YES=1 sh
# Preview the plan without changing anythingcurl -fsSL get.automem.ai | AUTOMEM_DRY_RUN=1 sh
The equivalent flags work on the npm package: npx @verygoodplugins/mcp-automem install --target existing --endpoint https://memory.example --clients codex,cursor --yes.
| Flag | Environment variable | Purpose |
|---|---|---|
--target | AUTOMEM_INSTALL_TARGET | local, cloud, or existing |
--cloud-provider | AUTOMEM_CLOUD_PROVIDER | instapods, railway, or other |
--clients | AUTOMEM_CLIENTS | Comma-separated agents: codex,claude-code,cursor,openclaw,hermes,grok |
--endpoint | AUTOMEM_API_URL | AutoMem HTTP API endpoint |
--api-key | AUTOMEM_API_KEY | Bearer token for authenticated deployments |
--local-dir | AUTOMEM_LOCAL_DIR | Local backend checkout path (default ~/.automem/server) |
--claude-code-mode | AUTOMEM_CLAUDE_CODE_MODE | plugin (default) or settings |
--cursor-mode | AUTOMEM_CURSOR_MODE | plugin (default) or files |
--hermes-mode | AUTOMEM_HERMES_MODE | mcp (default), provider, or both |
--yes / -y | AUTOMEM_YES=1 | Apply the reviewed plan without prompting |
--dry-run | AUTOMEM_DRY_RUN=1 | Print the plan, write nothing |
--no-agent-install | AUTOMEM_NO_AGENT_INSTALL=1 | Set up the endpoint only; skip agents |
Manual & advanced setup
Section titled “Manual & advanced setup”Prefer to run the backend yourself, or wire an agent by hand? Everything the installer automates, you can also do manually.
Deploy the AutoMem server yourself
Section titled “Deploy the AutoMem server yourself”- InstaPods creates a hosted pod and generates MCP configuration.
- Railway runs the AutoMem template and provides a public HTTPS domain.
- Docker Compose starts the API, FalkorDB, and Qdrant on your machine. The same guide covers bare Python for API development.
Connect an agent by hand
Section titled “Connect an agent by hand”The guided installer can connect to a server you deployed manually. On npm 0.16.0, use install. setup becomes an alias of install in the release after 0.16.0:
npx @verygoodplugins/mcp-automem install --target existingFor a manual MCP entry — for example Claude Desktop’s claude_desktop_config.json:
{ "mcpServers": { "mcp-automem": { "command": "npx", "args": ["-y", "@verygoodplugins/mcp-automem"], "env": { "AUTOMEM_API_URL": "http://localhost:8001" } } }}Add "AUTOMEM_API_KEY": "your-token" for authenticated (hosted) endpoints. Per-platform paths and snippets live in the Platform Guides.
Authentication
Section titled “Authentication”AutoMem accepts a token three ways, in order of preference:
# 1. Bearer token (recommended)curl -H "Authorization: Bearer YOUR_TOKEN" http://localhost:8001/health
# 2. Custom headercurl -H "X-API-Key: YOUR_TOKEN" http://localhost:8001/health
# 3. Query parameter (discouraged — tokens land in logs)curl "http://localhost:8001/health?api_key=YOUR_TOKEN"
These examples show the header and query forms only. /health accepts any token or none, so a 200 from it does not mean the token is valid. To check a token, send it to an endpoint that requires one, such as /recall?limit=1 (see Verify it worked).
Admin operations need an extra header:
curl -H "Authorization: Bearer YOUR_TOKEN" \ -H "X-Admin-Token: YOUR_ADMIN_TOKEN" \ http://localhost:8001/admin/...Troubleshooting
Section titled “Troubleshooting”| Symptom | Likely cause | Fix |
|---|---|---|
node is required from the launcher | Node/npm not installed | Install Node 20.19+ (nvm install 20), then re-run |
Installer says the package has no install | Old npm cache | The guided installer ships in @verygoodplugins/mcp-automem 0.15.0+; clear the npx cache or pin @latest |
| Local server won’t start | Port in use (:8001, :6379, :6333) | Stop the conflicting container (docker ps) or free the port, then re-run |
503 Service Unavailable | FalkorDB unreachable | Check FALKORDB_HOST / FALKORDB_PORT |
"qdrant": "disconnected" | Qdrant not configured | Expected — set QDRANT_URL to enable vector search |
401 Unauthorized | Wrong/missing token | Verify AUTOMEM_API_KEY; provide it without a Bearer prefix |
ECONNREFUSED on Railway | A platform set a non-8001 PORT while callers use :8001 | Pin PORT=8001 on memory-service |
| Tools don’t appear in your agent | Client not reloaded | Fully quit and reopen the agent (don’t just close the window) |
| One agent flagged “needs a manual step” | That agent’s CLI was missing | Run the printed fix command; the rest of the install still succeeded |
Next steps
Section titled “Next steps”- Connect more platforms — Platform Guides for Claude Desktop, Claude Code, Cursor, Codex, and remote MCP.
- Configuration reference — Environment Variables and Configuration for every setting and embedding provider.
- Use memory well — Memory Operations for tagging, importance, recall, and relationships.
- Production hardening — Railway and Docker for monitoring, backups, and scaling.